- Published on
From Spread MLE to Implicit MLE
- Authors
- Mingtian Zhang
1. Implicit Generative Models and IMLE
Implicit generative models are easy to sample from but often do not have a tractable likelihood. Let
and let denote the resulting distribution of . We can generate samples from , but evaluating may be impossible. The problem is even more severe when is supported on a low-dimensional manifold, because an ordinary density may not exist at all.
Implicit Maximum Likelihood Estimation (IMLE) trains such a generator without ever requiring access to its density. Given a data distribution , the population IMLE objective can be written as
For an empirical dataset , this becomes
In practice, IMLE repeatedly performs three steps:
- Sample a pool of latent codes .
- Generate candidates .
- For each data point, find its nearest generated candidate and update the generator to reduce the matched distance.
The matching direction is important: every data point selects a generated sample. This encourages the generator to cover all observed modes rather than only improving samples in regions it already generates well.
The expectation over averages over the random candidate pools produced by the model. The empirical average over the data can equivalently be viewed as an expectation under the empirical data distribution.
This objective does not immediately resemble a likelihood-based objective. The following sections show how it can be derived from a finite-sample approximation to spread maximum likelihood.
2. From an Ill-Defined KL to the Spread KL Divergence
Consider a data distribution and an implicit model distribution . A natural objective is the forward KL divergence, which, whenever both distributions admit densities with respect to the same base measure, can be written as
Since the first term does not depend on , minimizing the forward KL is equivalent to maximum likelihood:
That premise fails for the implicit generator above. Mapping a low-dimensional latent into a higher-dimensional observation space leaves supported on a lower-dimensional manifold, with no ordinary density with respect to the ambient Lebesgue measure. Worse, even when and both concentrate on low-dimensional manifolds, their supports may fail to overlap exactly, in which case is infinite or not meaningfully defined through ordinary density ratios.
Spreading the Distributions
Spread divergence addresses this by applying the same smoothing kernel to both distributions. Using Gaussian spreading,
the corresponding spread distributions are the convolutions
Gaussian convolution turns the original, possibly singular distributions into smooth distributions with densities over the full observation space. The spread KL divergence
is therefore well defined, whatever the supports of and happen to be.
Why Spreading Loses Nothing
Well-definedness alone would not be enough. Smoothing could in principle blur away exactly the differences we are trying to detect, leaving an objective that is finite but no longer informative about the original distributions. This does not happen for Gaussian spreading: the spread KL is a genuine divergence on the original distributions,
This holds for every fixed , and follows from the fact that Gaussian convolution is injective, so that already forces . See the spread divergence paper for the proof and for the general conditions a noise distribution must satisfy for its spread divergence to be a valid divergence.
So nothing is lost by spreading: driving the spread KL to zero matches the two distributions we actually care about, even though may itself be ill-defined. What remains is to turn this divergence into something we can optimize.
3. Spread Maximum Likelihood
Expanding the spread KL exactly as before,
the first term again does not depend on . Minimizing the spread KL is therefore maximum likelihood under the spread model, which gives the Spread Maximum Likelihood objective
Because the two objectives differ only by a -independent constant, the identifiability of the spread KL carries over directly. Assuming the data distribution is realizable,
Spread MLE is thus not a compromise objective that merely happens to be computable. Its optimum recovers the unspread data distribution, so it estimates the same thing ordinary MLE would have estimated had the latter been well defined.
For an implicit model, the spread density is a Gaussian mixture over model samples,
which is a smooth density even when the original model is implicit or singular. Substituting it in,
This is a valid likelihood objective, but the inner expectation is generally intractable.
4. A Finite-Sample Approximation
Draw samples from the implicit model:
The spread density can be approximated by a finite Gaussian mixture:
This gives empirical spread MLE, the objective at finite ,
Because the finite mixture is an unbiased estimator of the spread density, Jensen's inequality gives
This is the same general construction used in multi-sample likelihood bounds such as the importance weighted autoencoder: a finite Monte Carlo average is placed inside the logarithm, and the expectation of the resulting log gives a lower bound on the exact log marginal likelihood.
As , the finite mixture approaches the exact spread density under suitable conditions.
5. The Small-Noise Limit
Consider the core log-sum-exp term:
Fix , and for a moment. As , the largest exponential term dominates, so that pointwise
The same limit performs two operations at once:
- The data noise disappears because
- The soft Gaussian responsibilities become a hard nearest-neighbour assignment.
Both the inside the logarithm and the additive constant are killed by the factor, so rescaling by yields
which is exactly the population IMLE objective of Section 1. This last step exchanges the limit with the expectation, which is not automatic: assuming and have finite second moments, and under suitable uniform-integrability conditions, the limit may be passed through the expectation. Bounded , or a compact parameter set with uniformly bounded second moments, is enough in practice.
Replacing by the empirical distribution of gives ,
Note that the rescaling factor is negative, which is what reconciles the two directions of optimisation. Therefore, at the objective-function level, IMLE is the small-noise limit of the rescaled finite-sample spread likelihood. Each training example is matched to its nearest generated sample, and the generator is trained to reduce those distances.
6. The Connection
The relationship can be summarized as
More explicitly, working throughout with the rescaling of the previous section,
The first step is a finite Monte Carlo approximation. The second is an exact pointwise limit; passing the limit through the expectation requires standard integrability conditions. The inside the logarithm contributes , which vanishes as and so leaves no trace in the limit.
7. Empirical Spread MLE
Read the other way round, the derivation says that empirical spread MLE (SMLE) contains IMLE as its special case, and so is a strict generalization of it: the same nearest-sample machinery, with left as a free knob rather than sent to zero. Is that knob worth having?
Pleasingly, the whole objective is four lines, and selects the limit:
def SMLE_loss(X, Y, sigma):                     # sqdist(A, B)[i, j] = ||a_i - b_j||^2
    if sigma == 0:                              # the IMLE limit
        return sqdist(X, Y).min(dim=1).values.mean()
    Xt = X + sigma * torch.randn_like(X)        # spread the data too
    return -torch.logsumexp(-sqdist(Xt, Y) / (2 * sigma**2), dim=1).mean()
Everything -independent has been dropped — the mixture's , the Gaussian normaliser, and the scale — since at fixed none of them move the minimiser. IMLE is then not a separate method to implement; it is the branch you get by setting the knob to zero.
What the data noise actually does
The in is a second Monte Carlo source on top of the pool , and it is worth asking what it contributes, because the integral can be done in closed form. Expand the exponent,
and integrate against . Completing the square in leaves a Gaussian integral, and
Note the : spreading the data has turned the width- kernel into a width- one. That is exactly what it should do — the kernel is being evaluated at a point that itself carries width- noise, and two Gaussians of width convolve to one of width . The prefactor is -independent and joins the other discarded constants.
The catch is that the logarithm sits outside the expectation, so this identity does not simply substitute in. Applying it exchanges with , which by Jensen gives a bound rather than an equality:
The right-hand side is the same objective evaluated on clean data at noise level . So the choice of whether to sample the data noise is not a separate design axis at all: dropping it keeps you inside the same one-parameter family and merely moves you along the axis by a factor of , up to a Jensen gap that closes as . The sweep below is robust to that choice for the same reason.
What sampling does cost is variance. Under the rescaling the noise enters the exponent as , so the cost shrinks with rather than growing: measuring the gradient variance over 300 replicates on the setup below, evaluating at the clean reduces it by at , at , and only by , where resampling the pool dominates instead.
A 2D check: the data are eight Gaussians on a ring, the generator is a small MLP mapping to , and a fresh pool of candidates is drawn at every step so the objective matches the above. Between runs the only thing that changes is . Full code here.
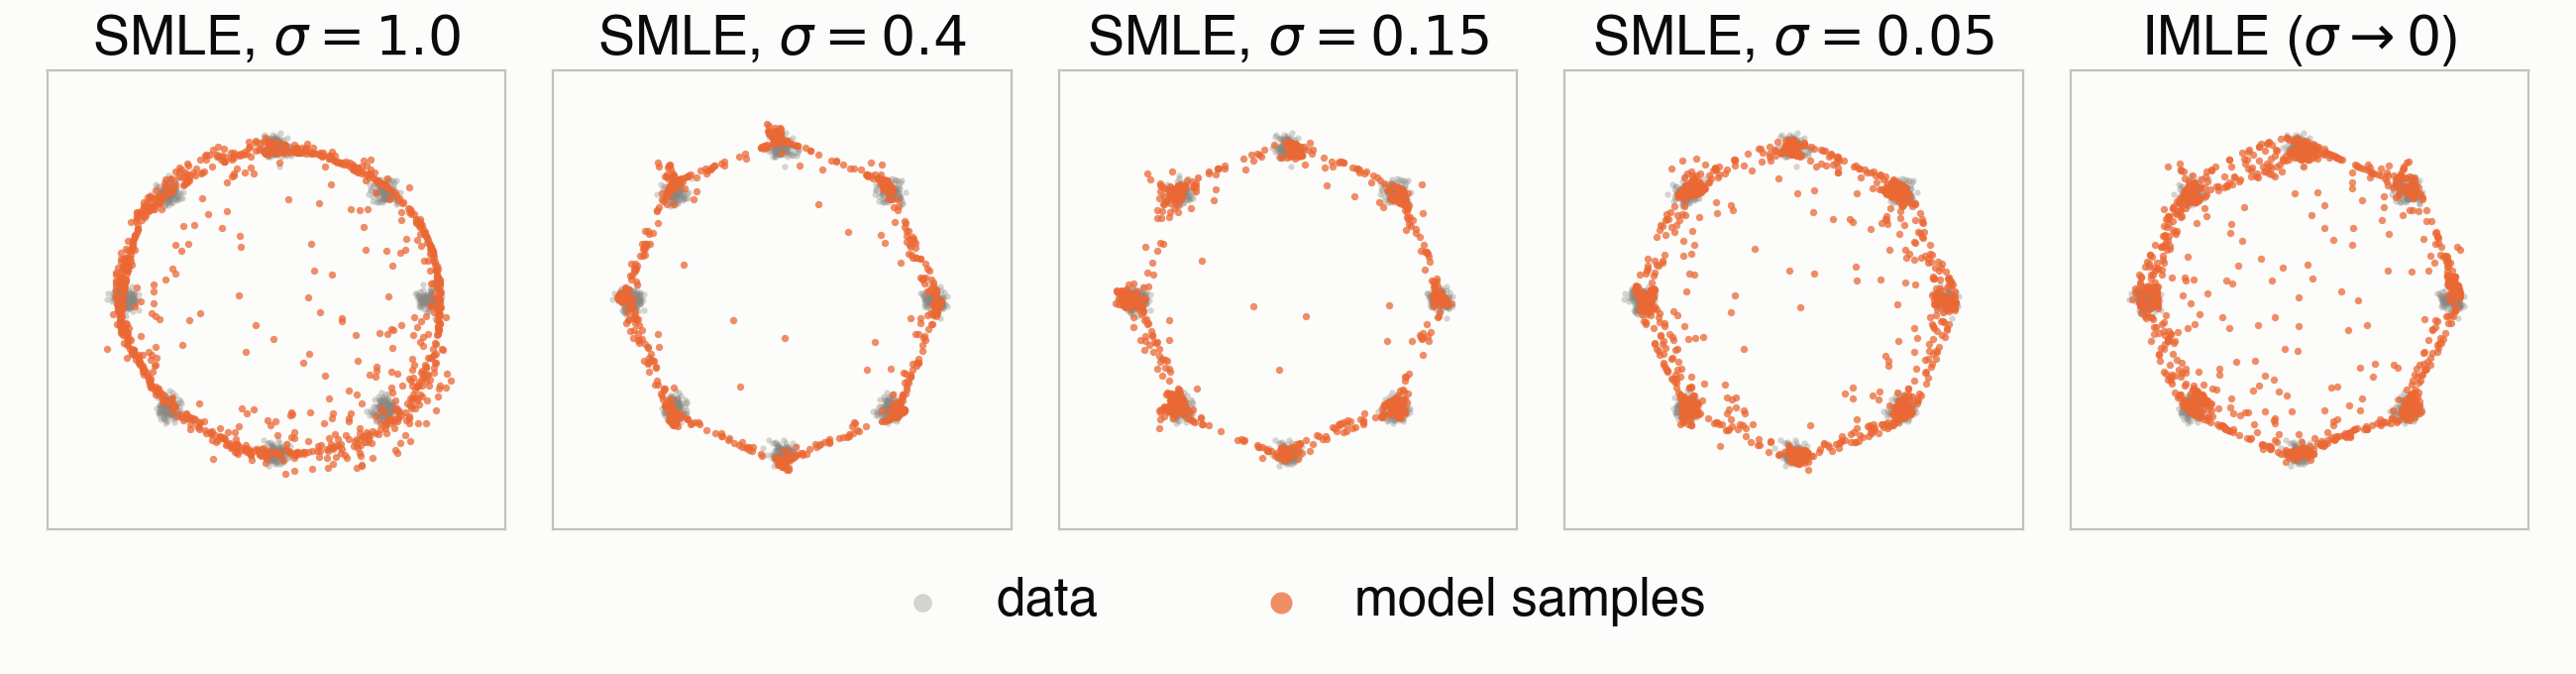
At the samples are visually indistinguishable from IMLE, down to the filaments the generator strands between modes. The limit is not a formality — the two objectives really do train to the same solution.
The interesting part is in between. Look again at the sweep above: at the samples sit tightly on the eight modes, and as shrinks they progressively smear out into the gaps, with IMLE the loosest of all. The hard limit is not the best member of the family — keeping the log-sum-exp is what buys the cleaner samples.
The mechanism is visible in the gradient. Both objectives pull candidates toward data,
and differ only in : empirical spread MLE at uses the mixture responsibility , IMLE a one-hot indicator on the nearest candidate. Under one-hot weights a candidate receives no signal at all unless it wins some match, so a sample stranded between modes can stay there; under soft weights it still feels a pull from every nearby data point.
At the other extreme washes the modes out completely. That is not a failure of the spread divergence — the identifiability of Section 2 holds at every fixed — but a finite-, finite-budget optimisation effect: the objective becomes so flat that the gradient cannot resolve structure at the scale of the modes. Useful is a middle band, and IMLE sits at one end of it.
8. What Spread MLE Buys
Three things come out of the derivation.
IMLE stops looking arbitrary. Its design choices are not choices at all; each one is forced by the construction. Generated samples act as mixture centers because the spread model is a mixture centred on model samples. Squared Euclidean distance appears because the spreading kernel is Gaussian — a different kernel would give a different cost. Each data point takes its nearest sample because that is what the log-sum-exp degenerates into. The expectation over freshly drawn pools is there because the mixture is a Monte Carlo estimate, not a fixed set. And the mode-covering behaviour follows from the direction of the match, data to samples, which is the direction a likelihood of the data under the model demands.
The estimator gets a target. A nearest-neighbour distance on its own is a heuristic: minimising it does not obviously estimate anything. Spread MLE is a likelihood, and by Section 2 its optimum is at every fixed — the unspread data distribution, the same thing ordinary MLE would target if it were well defined. That is what makes this a principled route to fitting a singular implicit model rather than a convenient distance.
becomes a knob rather than a constant. IMLE is the corner of a one-parameter family, and on the toy problem the corner is not the best place to stand: put nearly all samples on the modes where IMLE strands many of them in between. Two things are given up in the limit. The finite-sample objective is only a lower bound on spread likelihood, with a Jensen gap at fixed ,
and the hard assignment throws away every soft responsibility but one. Neither loss is forced on you — they are the price of the corner, not of the framework.
So the summary cuts both ways:
IMLE is the zero-noise hard-assignment limit of a finite-sample approximation to spread maximum likelihood — and spread MLE is the likelihood that limit came from, identifiable at every , with the interior of the family worth exploring.
References
- Spread Divergence — Mingtian Zhang, Peter Hayes, Thomas Bird, Raza Habib, David Barber. ICML 2020.
- Implicit Maximum Likelihood Estimation — Ke Li, Jitendra Malik. arXiv preprint, 2018.
- Importance Weighted Autoencoders — Yuri Burda, Roger Grosse, Ruslan Salakhutdinov. ICLR 2016.
Citation
@misc{zhang2026spreadmle,
  title  = {From Spread MLE to Implicit MLE},
  author = {Zhang, Mingtian},
  year   = {2026},
  month  = {August},
  url    = {https://mingtian.ai/blog/SpreadMLEtoIMLE},
  note   = {Blog post}
}